
This is another in an occasional series on trading and quantitative finance.
Sometime this spring I did something I had been putting off for two decades, and I mean the title literally. Since 2005 I have kept three repositories of research ideas. Papers, links, half-formed signals, a note from 2 a.m. that says only “iceberg detector — trade size decay?” and an attachment I can no longer open. That was the year I walked away from a famous pod shop’s IP contract and started building execution systems that belonged to me, which is why the earliest items in the archive are about detecting hidden orders rather than about anything so grand as a theory of markets. I never intended any of it as a dataset. It was a place to put things so I would stop losing them.
It turns out that when you put things somewhere for twenty-one years, and each thing arrives with a date, you have built a dataset whether you meant to or not. There are 1,163 dated items in there. And when I finally coded them by year and theme and stared at the resulting heat map, I found that what I had accidentally recorded was not a list of good ideas. It was a record of my own attention moving, across several market regimes, under adversarial conditions, with real money downstream of every shift.
That record is one evidence base for a chapter I have just published in an IntechOpen volume on investor behavior and investment strategy. This post is about the one thing the archive says that I did not expect it to say.
What the archive is, and what it emphatically is not
Let me kill the obvious objection before it gets comfortable.
This is an N of one. It is a record of what a single practitioner chose to save, filtered through his interests, his blind spots, his employment history, and whatever he happened to be reading that week. It is not a random sample of anything. It is not evidence that any of these ideas made money. Selection bias is not a bug in this dataset; selection bias is this dataset.
Good. That is the point.
A published survey tells you what a field decided was worth writing down. An archive like this one tells you something different and, for a practitioner, more useful: what somebody with capital at risk kept coming back to, across market environments that had no obligation to be kind to him. An idea that shows up in 2007, again in 2013, and again in 2022 has survived three different worlds. An idea that shows up once and never again has told you something too.
So: not a performance ranking. A persistence ranking of research attention. A weaker claim than “these things work,” and a stronger one than “these things were fashionable.”
The arc nobody plans
The first surprise was the shape. The heat map itself is in the chapter, which is open access and free — I would rather you went and looked at it than took my word for the pattern. The caveats are with it: items can carry more than one label, cells are normalized within year, and 2026 is partial.
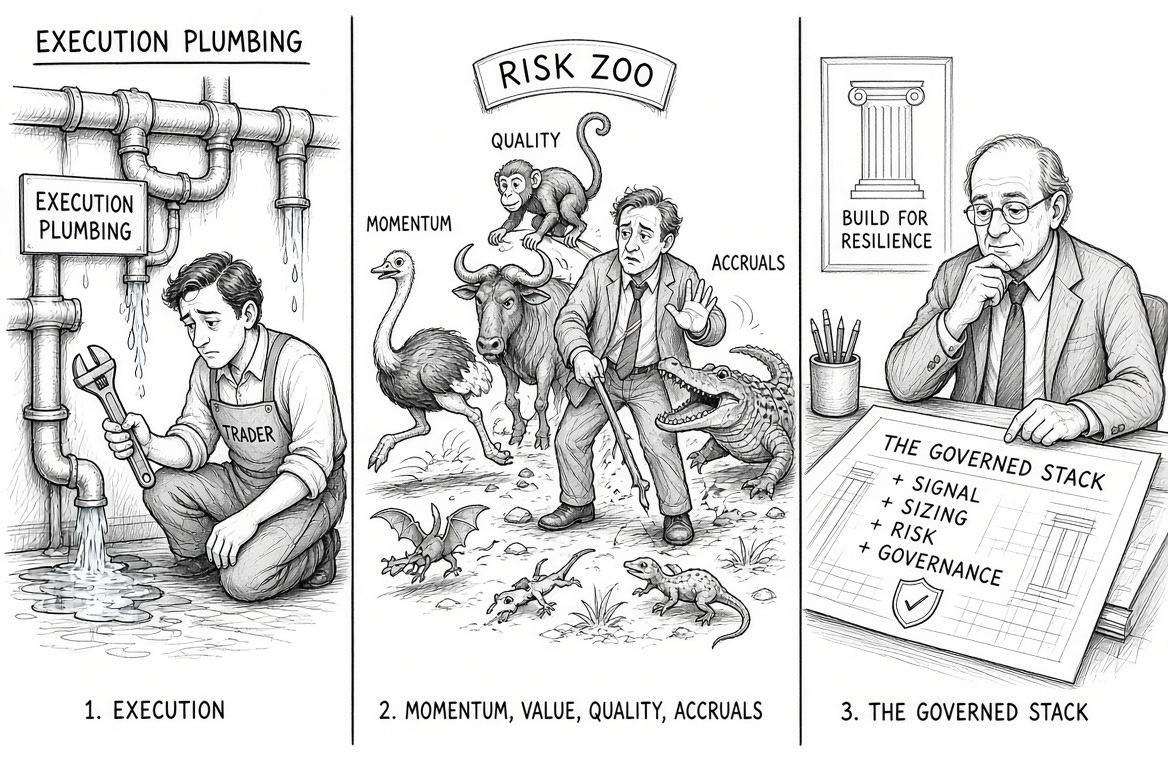
The early years — 2005 through roughly 2011 — are almost entirely plumbing. Iceberg detectors. Trade-size models for inferring informed flow. Intraday signals. Spread estimation from OHLC data. Pairs logic and scalper logic. Nothing in there asks why markets do anything. It is all measurement and execution, because that is what was missing.
The middle years, call it 2012 through 2018, are the factor years. Momentum. Value. Quality. Accruals. Piotroski. Factor timing. The factor zoo, and then the papers about how the zoo had gotten out of hand. This is the period when I still thought the question was what predicts returns.
And then from 2019 onward the archive changes character entirely. Composite alpha construction. Risk parity arguments. Volatility state. Regime conditioning. Downside correlation structure. Drawdown metrics.
Early years: build what was missing. Middle years: chase what predicts. Later years: conclude that the chase was the mistake.
I did not design that trajectory. I did not notice it happening. I saw it only when the years were laid out side by side, at which point it was so obvious that I felt slightly foolish for having needed a heat map.
The obvious objection is that this is occupational rather than intellectual — that the reading simply follows the job title. But that gets the causality backwards. Nobody assigned me to plumbing in 2005. I needed plumbing, because you cannot run a portfolio without it, and it did not exist. That is what a bottleneck is: the thing that has to be built before the next question can even be asked. Once execution worked, finding something to trade became the constraint. Once I had spent years looking, what became the constraint was the discovery that the looking had been aimed at the wrong thing.
So the archive was never tracking my job description. It was tracking the order in which the constraints bound. Which is precisely what you would want a record of practitioner attention to do, and considerably more interesting than a reading list.
I want to be careful about what the heat map can and cannot carry. It is a seismograph of attention, not a performance ledger. It cannot show that stacks beat signals. What it can show is that as responsibility widened, the recurring problem moved from finding an edge to keeping one alive. The stronger claim comes from the failures, and I will get to one.
Momentum, and the word “housed”
The most persistent theme is momentum. It appears in 17 of the 22 annual columns, in every form — time-series, cross-sectional, factor, cross-asset, option momentum, acceleration, reversal. If you want a one-word answer to “what recurs,” it is that word.
But here is the more interesting pattern, and the reason the archive is worth more than a citation count. The momentum papers appear throughout. The papers on momentum crashes, and on blending momentum with valuation, start piling up after about 2015 and never stop.
The lesson two decades of my own attention encodes is not “buy momentum.” It is: momentum works, but it must be housed correctly. And how it fails depends on which momentum you mean, which is why the archive’s habit of hoarding all of them turns out to matter. Cross-sectional equity momentum dies on the violent rebound after a stressed market, because it is short the beaten-down names at precisely the moment they scream off the bottom. Time-series trend following frequently does its best work during those same persistent crises, and dies instead on whipsaw — on the reversal that arrives the week after it commits. They fail on different days. What they share is that both get worse when liquidity thins, and worse again when crowding makes the rebalance expensive enough that everyone tries to leave through the same door on the same afternoon.
Which reframes everything else. Value and quality can obviously stand alone as return sources; what the archive records is that they increasingly show up as stabilizers, the thing that stops momentum from degenerating into pure extrapolation. Volatility, breadth, sentiment, and macro are not forecasts; they are state variables that tell you whether your other signals are operating in a friendly environment or a hostile one. Microstructure is not a technical afterthought; it is the boundary between paper alpha and tradable alpha.
The durable unit is not the signal. It is the stack: signal, sizing, execution, risk control, monitoring, and the governance that decides when to override the other five.
Let me be exact here, because there is a lazy version of this claim and I would rather not be caught holding it. Architecture is not a substitute for having something to trade. A beautifully governed portfolio with nothing in it is an expensive way to earn nothing, and I have met several.
But let me be equally exact about what I am not claiming, because the obvious reading is wrong. I am not saying I got better at forecasting and then decided governance mattered more. I stopped forecasting returns more than a decade ago. I have argued at length elsewhere that the hunt for a durable alpha source is largely a hunt for something that is not there, and nothing in twenty-one years of saved ideas has talked me out of it. The middle stretch of this archive is not a record of learning what predicts. It is a record of finding out that the question was wrong.
What survives that discovery is not a forecast. It is a rule for taking exposure conditional on a state you can actually measure, sized so that being wrong is survivable.
The sad part is that pouring money and brain hours into predicting the market is completely unnecessary to achieve success. Trading is about probability and risk management, not about predictions. You do not need to know what happens next in order to make money. You need to know how to size a position, under what conditions to hold one at all, and how to be wrong cheaply.
The conservation law nobody writes down
Here is where I want to plant a flag, because I think this is the gap that behavioral finance keeps walking up to and then declining to cross.
Behavioral finance is very good at the first step. Attention is scarce, so information gets incorporated in stages. Investors overweight private signals, disagree, and trade too much. They realize gains early and defer losses. They extrapolate. They herd, especially when career risk is involved. All of this is well documented and, as far as I can tell, true.
But every one of those mechanisms produces a pattern in prices. And a pattern in prices is not a return.
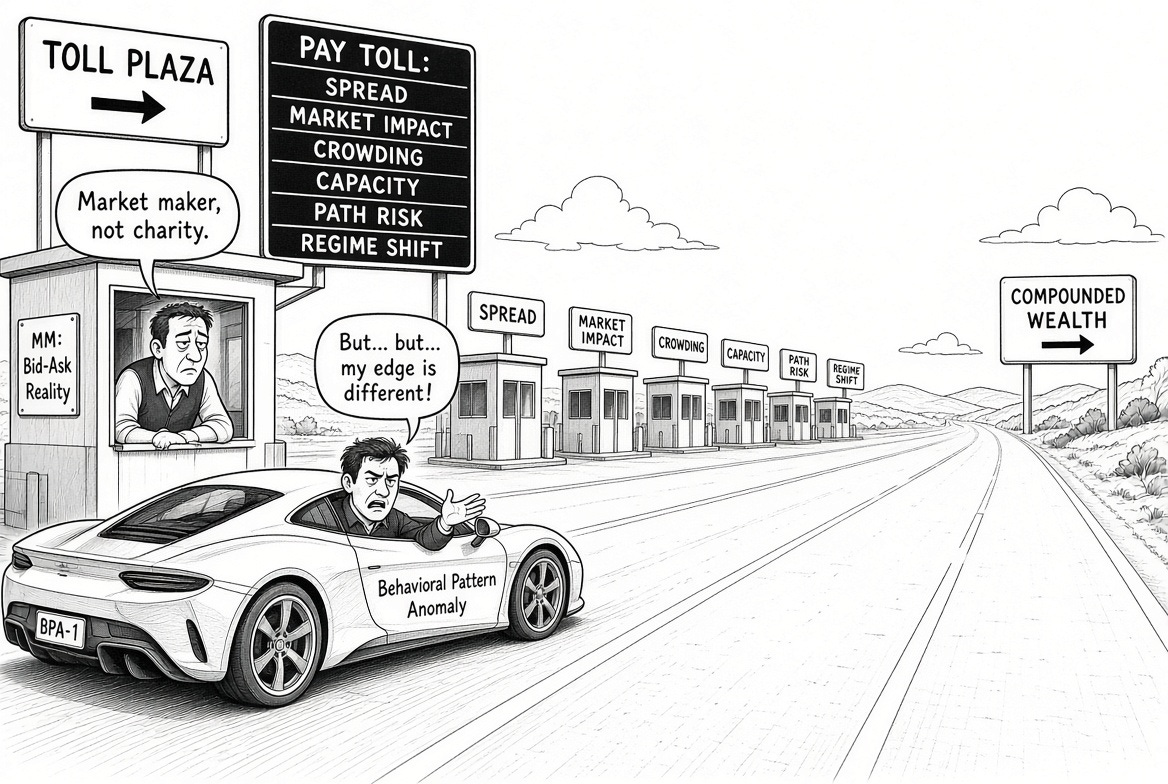
Between the pattern and your P&L sits a toll booth, and the toll is collected in several currencies. Spread and market impact. Borrow cost. Capacity — how much money the effect absorbs before it stops being an effect. Crowding, which is capacity’s angry cousin. Regime dependence, because the pattern is conditional and the conditions move. And path risk, which is the possibility that the sequence of returns bankrupts you before the mean arrives.
Now ask the conservation-law question. If a behavioral bias creates a measurable pattern, and the pattern does not show up as compounded wealth, where did the value go?
There are two answers and only two. Either the edge was never there — a false positive, a specification artifact, noise wearing a t-statistic — or the toll booth collected it. The anomaly literature is largely occupied with the first question. Practitioners find out about the second with money.
That is what a conservation law actually buys you. It does not tell you which channel the energy went down. It tells you the books balance, and that no amount of admiring the pattern will make the arithmetic come out differently.
There is also a seventh currency, and it rarely turns up in the anomaly papers. It has a literature of its own — implementation shortfall, operational risk — but that literature lives in a different building from the alpha research, and the two do not visit often.
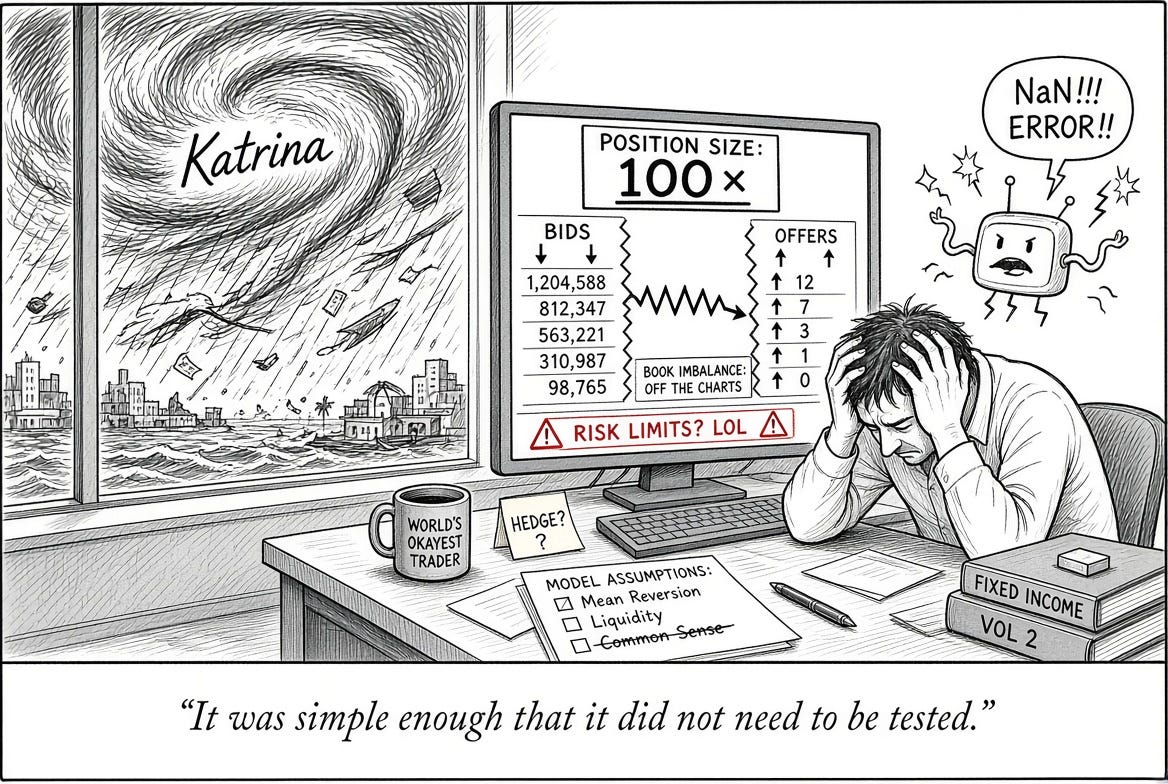
In 2005 I was supplying signals to a market-neutral long-short book at a prop shop, trading the firm’s capital. A separate team, over which I had precisely no authority, was responsible for turning those signals into orders. The people involved shall remain nameless. On the day Hurricane Katrina made landfall, that team pushed a change to the trade placement algorithm. The change was simple enough, they judged, that it did not need to be tested.
It was not simple enough.
The algorithm began entering positions at roughly one hundred times their intended size. And unbalanced. Which is to say that a book whose entire risk architecture rested on being market neutral was, for the duration, not market neutral in any respect whatsoever. It had become a large, arbitrary, directional bet, placed by software, during Hurricane Katrina, while natural gas was coming apart in the Gulf.
It took about an hour to lose the book’s profits for the year.
Note carefully what did not happen. The signals were not wrong. The mechanism was real, the pattern was real, the edge was real, and it had been converting into money all year. Not one of the six line items above laid a finger on it. The alpha died in the gap between my research and the exchange, inside a system I did not control, because of a decision I was not consulted on.
And here is the part that bothers me more, twenty years on, than the money ever did.
I never ran a post-mortem. I was far too angry at the time to conduct one, and the precise sequence is now lost to whatever passes for posterity in this business. Every material loss I have taken since 2016 has produced a post-mortem, because the post-mortem is the machine that converts a loss into a system improvement. It is the only mechanism by which losing money is ever worth anything.
You cannot run a post-mortem on a system you do not control. You cannot diagnose it. You cannot fix it. You cannot stop it recurring. You can be told what happened, by the people who did it, and then go back to feeding signals into the same machine.
Capacity, crowding, and cost are the tolls the anomaly literature prices. The operational chain between your signal and the exchange is the one it doesn’t — and that toll takes your ability to learn along with your money.
Operational failure is the violent case, and it is mercifully rare. The ordinary case is slower: a real signal dies by degrees, which is also why single-signal investing usually fails. Efficacy varies by regime. Expected return compresses as capital arrives, and unwind risk rises with it. Turnover and slippage grow faster than linearly exactly when liquidity thins, which is exactly when the signal is shouting at you to trade. And relationships drift, because the microstructure of 2005 is not the microstructure of 2025, and pretending otherwise is a decision rather than an oversight.
One special case deserves its own paragraph, because it has eaten more good funds than the rest combined: market neutrality is incomplete neutrality. Dollar neutral is not liquidity neutral. Beta neutral is not crowding neutral, funding neutral, or crisis neutral. Quantitative market-neutral books tend to hold similar positions because they use similar data, similar models, and similar optimizers; when one is forced to deleverage, the selling moves prices against everyone else’s identical positions, which forces more deleveraging. August 2007 and March 2020 are the canonical exhibits. In both, dollar-neutral strategies took correlated losses at precisely the moment the hedging architecture was supposed to be doing its job.
The hedge was against the wrong thing. It was hedged against the market. It was not hedged against the other people running the same hedge.
It is not a controlled experiment — nothing in this business ever is — but consider what happened inside a single firm in 2020. Renaissance’s Medallion fund, open only to current and former partners, returned 76% net. Renaissance’s institutional equities fund, RIEF, lost about 19% on the year. RIEF is not a market-neutral book, incidentally — it runs long-biased with a low target beta — and that is rather the point, because what separated the two funds was not the hedge. Same firm. Same software. Same senior management team. The difference, per an investor who was in both, came down to holding period and risk architecture: RIEF held positions for six months to a year and hedged with factor-based risk models, while Medallion turned over fast enough to adapt as the regime changed. Medallion also ran more leverage, and the same investor was clear that almost nothing else about the two funds was correlated. So: not a clean instrument. Nearly a hundred points of spread inside one firm is still a difficult thing to pin on the signals.
And here is the line from that investor that I would put on a wall: there was nothing wrong with RIEF’s models.
I believe him. But in trading, the world is the test set. The return model was never the whole system.
Risk management is not a tax
The standard framing treats risk management as a drag on return — the thing you do to sleep at night, paid for in basis points.
In a live book the opposite is true. Risk management preserves the horizon over which alpha is permitted to operate. A valid signal with a bad drawdown profile does not underperform. It gets liquidated, or its manager capitulates, and then it produces nothing at all, forever. There is no partial credit.
Which is not a license for threshold rules. Mechanical drawdown cutoffs mostly fail, and the standard metric used to evaluate them is arithmetically broken in a way that ranks catastrophes as mild; I went through all of that in January and won’t repeat it. The line worth carrying forward is that a generic risk rule is not risk management. A rule that knows nothing about your entries, your instruments, or your holding periods cannot possibly know when to override them.
What a risk framework can rest on is a single empirical asymmetry that I think remains underappreciated even by people who know it. Short-horizon volatility is dramatically more predictable than short-horizon returns.
An illustrative check, SPY from February 1993 through April 2026. Regress this month’s realized volatility on last month’s: R-squared of roughly 0.41. Now run the analogous regression for returns, this month’s on last month’s: R-squared of roughly 0.00003.
Four orders of magnitude. That is not a difference of degree. It is a difference of kind. The exact coefficients depend on sample, universe, frequency, and estimator, and I would not defend the third decimal place of either number. I will defend the gap between them until the sun burns out.
This is the volatility clustering Engle formalized and took a share of the 2003 Nobel for, and its design implication is direct: model risk, not return. But note the limits. GARCH and its descendants fail most reliably at regime transitions — at the volatility spikes, at the collapses that start recoveries — which is to say, exactly when you need them. So the right operation is classification, not point forecasting. Do not stake the book on a number the model produces most confidently right before it is most wrong.
My own 2020 is a process story rather than a forecasting story, and I want to be precise about that, because I had no idea what was coming. Nobody did. What I had by then — having started trading my own capital in 2016 and built every piece of the stack myself, for reasons the reader can probably now guess — was a risk classification that did not require me to know. It was built to identify which state we were in, not to predict where we were going. Exposure came down partway into the drawdown and went back up a few weeks later, when the state changed back. No judgment call was involved at either end, which was the entire design intent.
Whether that was the right thing to do in any particular week is a separate question from whether the machinery did what it was built to do. The machinery did what it was built to do.
And it is the reason I own my plumbing now.
The protocol is a list of things that have already gone wrong
The chapter proposes a research-to-portfolio protocol. I want to state it in the only form I find useful, which is to attach each step to the specific disaster it exists to prevent.
Mechanism. Start from a behavioral or structural reason, not a mined predictor. Otherwise blind search gets mistaken for explanation. The exemption here is narrow, and you do not qualify for it: unless you have ninety PhDs on the payroll, something like a Markov chain running underneath the whole apparatus (if you have to ask, don’t even try), and a fund so uninterested in your money that it stopped accepting outside capital in 2005, you do not get to skip the mechanism. Renaissance can brute-force its way to an answer nobody on the premises can explain in words. You cannot.
Proxy. Translate the mechanism into transparent variables with documented measurement error. Otherwise vague psychology becomes an unverifiable signal.
Chronology. Test out of sample, strictly in date order. Otherwise the future leaks into the past.
Costs. Stress turnover, market impact, and execution delay. Otherwise paper alpha survives purely on the strength of costs you declined to model.
Integration. Combine signals with shrinkage and regime-conditioned weights. Otherwise you have bet the firm on one noisy input.
Governance. Set the leverage limits and the drawdown response ex ante, because otherwise the discretionary override gets invented at the moment of maximum stress by the person least qualified to invent it — you, at 3 a.m. Set the kill switches separately and mechanically, and note that these are not the drawdown thresholds I spent an earlier section arguing against: a kill switch fires on operational failure, corrupted data, a breached exposure limit, a model invalidated rather than merely disappointing. Had one been watching position size against intent on a certain morning in August 2005, this essay would be shorter.
Audit. After deployment, track signal decay, crowding, and slippage against backtest. Otherwise slow deterioration gets filed as temporary noise until it isn’t.
Governance matters more for behavioral strategies than for any other kind, for a reason that is almost too neat: the biases you are exploiting in the market are running in your own head at the same time, on the same inputs.
Coda: the humility premium
Any chapter claiming to take academic finance seriously has to reckon with Chen, Lopez-Lira, and Zimmermann, who mined 29,000 accounting ratios by brute force and found that the resulting predictors survive out of sample about as well as a couple of hundred peer-reviewed ones from the top journals. I went through that result in detail here and will not relitigate it.
What matters for this argument is narrower. It looks superficially like a refutation of “mechanism first,” and it isn’t. Peer review improves measurement, interpretation, transparency, error detection. It is simply not a test of tradability, and was never built to be. And “mechanism first” never claimed that theory guarantees the result. The mechanism supplies the search direction and the interpretive frame. It does not supply the blessing. The data still has to speak, and it is under no obligation to say what you hoped.
What theory cannot do under any circumstances is get you around cost, capacity, regime dependence, and path risk. Those bind regardless of how elegant the story is. Some patterns do carry real content; that has never been the dispute. What they do not carry is a durable edge — which is exactly why the game is exposure and survival rather than collection.
And then there is the term no quantitative framework contains.
A strategy that does not fit your temperament will not be executed. Not “will be executed poorly” — will not be executed. A risk-averse person will not hold momentum through a crash. A patient value investor will not trade intraday reversals. They will deviate at precisely the wrong moment, and they will deviate for the most convincing reason available, which is that every instinct they have will be screaming that something is wrong. I have said this to aspiring quants often enough that it has become a refrain, and I have watched it happen to good people with valid strategies more times than I can count, and I have never once seen the strategy win the argument.
Which returns us to where the chapter starts. The same forces that create mispricing out there — loss aversion, overconfidence, scarce attention — are operating in here, on you, in real time, while you decide whether to override the model. A strategy design that ignores the internal dimension is incomplete no matter how good its Sharpe looks in the deck.
One last thing the heat map shows, which I have deliberately left alone until now. The newest and fastest-growing cluster in the archive is machine learning and language models applied to return prediction. The evidence there points in two directions at once: these models can extract real information from news, and they also over-extrapolate recent trends and exhibit miscalibration that looks uncomfortably human. Which stands to reason. They were trained on us. AI may not abolish behavioral finance; it may industrialize it. There is a post in that, and it is coming.
But whatever that cluster turns into, it arrives at the same toll booth as everything before it. Cost. Capacity. Decay. Crowding. Governance. A language model does not get to skip the queue because it is new.
Which is the archive’s actual verdict, and the reason that twenty-one years and 1,163 saved items produced a conclusion about architecture rather than a conclusion about signals: the unit of survival is not the signal. It is the governed architecture that carries it.
The chapter is open access and free: “From Investor Psychology to Strategy Design — Evidence, Mechanisms and Implementation,” IntechOpen, DOI 10.5772/intechopen.1016617. The drawdown work behind it is “The False Promise of Drawdown Rules: New Evidence and a Better Framework,” Journal of Portfolio Management, 2025, 52(1), 145–161, DOI 10.3905/jpm.2025.1.765.
Related in this series: The Stop-Loss That Stops Gains on why drawdown rules fail and what to use instead. The Simplicity Tax on what happens when the binding constraint turns out to be computational rather than preferential. The Emperor Has No Alphaon what peer review does and does not certify.
Disclosure: I am the managing member of VS Asset Management, LLC, which uses some of the methods discussed here. Nothing above is a recommendation or a solicitation. Past performance is not indicative of future results, and I would gently suggest you not need to be told that twice.
If you enjoyed the argument that the governing architecture matters more than the component it carries, you may enjoy an equally uncomfortable question about an equally cherished story: my book,The Science of Free Will.
Also here: The Paradox of India and the full India series, on why the world’s largest democracy keeps producing outcomes nobody chose. And Albion, on Britain’s institutional decline — which I first noticed in 1979 and which has, if anything, accelerated.
Thanks for this gem again! Learnt a lot just by reading it, keep writing, Dr Varma, you’re a blessing to this world!